Memory and Context Management in Long Research Sessions
Raw web content and stale information degrade AI agent performance far more than token limits do.
AI agents don't fail because the context window fills up. That's the story everyone reaches for, and it's wrong. Most agents break long before they hit any token ceiling, because what they're reading has quietly gone bad: bloated, buried, stale, or poisoned. Andrej Karpathy named this problem in June 2025, calling it "context engineering," the delicate art and science of filling the context window with just the right information for each step. The word choice matters. Art and science, not a switch you flip once and forget.
Two pieces of research make the point sharper. Chroma Research described "context rot" in July 2025: model performance drops as input length grows, measurably, even when the model never runs out of room. Stanford researchers documented "lost in the middle": models read the start and end of a long input just fine, but anything buried in the middle gets skimmed at best, ignored at worst. Databricks found correctness starting to slip around 32,000 tokens, nowhere close to any modern ceiling.
And the ceilings are high. Claude Opus 4 sits at 200,000 tokens. GPT-4o handles 128,000. Gemini's flagship models go up to 1 million, with some configurations reaching 2 million. None of that headroom matters if the problem is something other than size. It's content. The LongMemEval benchmark backs this up directly: long-context models lose 30 to 60 percent of their performance on its single-session test, and even the best commercial systems only manage 30 to 70 percent accuracy on conversation histories around 115,000 tokens per question. A pipeline that looks sharp on turn three can be unreliable by turn fifteen, not because the model got dumber, but because everything it's reading got worse.
How token bloat accumulates in a real multi-step web research pipeline
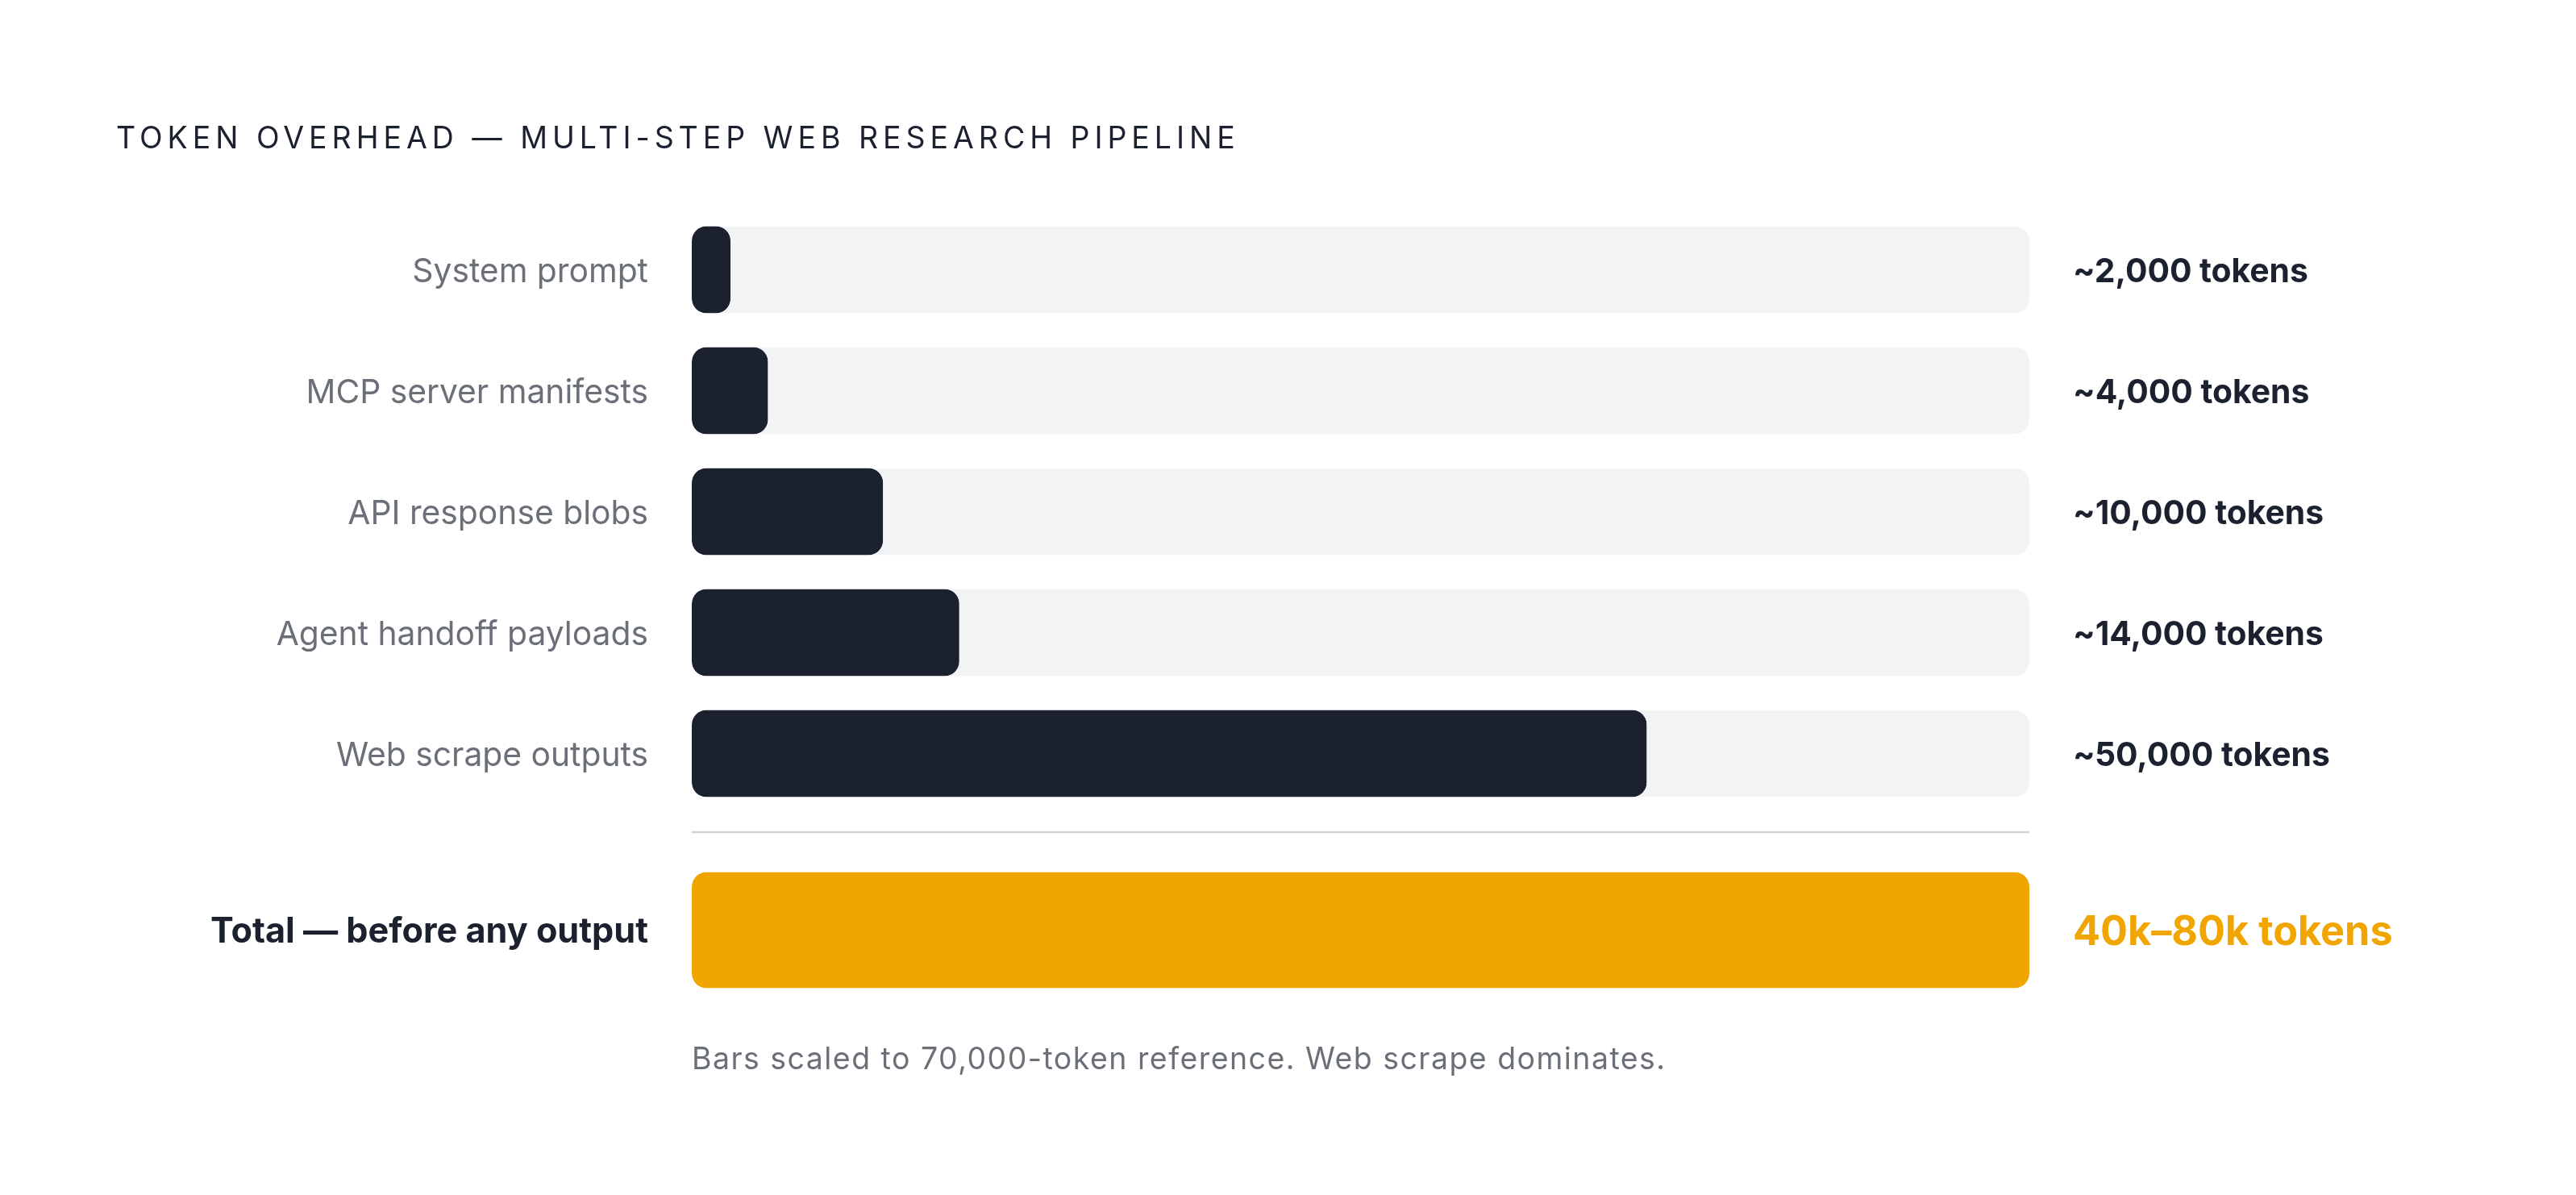
Token overhead doesn't show up all at once. It builds from several sources running at the same time, and each one adds up faster than it looks.
System prompts run around 2,000 tokens. Each MCP server manifest tacks on roughly 3,000 more. Then there's the big one: web scrape outputs, which can run to tens of thousands of tokens per call, depending on the page. That variance alone tells you the problem, since a single scrape can differ dramatically based on nothing more than which site got hit. Add in API response blobs and the handoff payloads agents pass to each other, and a multi-agent pipeline can be sitting on 40,000 to 80,000 tokens before it's written a single line of final output.
Web content is the worst offender, and it isn't close. Raw HTML carries far more tokens than the same content converted to clean Markdown, sometimes by an order of magnitude. A large share of web data is unstructured, which means most of what a scraper pulls back isn't something a model can reason over cleanly without cleanup first. Anyone still feeding raw HTML into a pipeline and calling it a data strategy is paying a tax they don't have to pay.
It gets messier. The same URL can return different content on two back-to-back scrapes, thanks to A/B tests, client-side rendering, lazy-loading, or geo-targeting. An agent that retries a failed fetch doesn't get a clean second attempt. It gets a slightly different version of the same page, and now it's carrying both. Left unchecked, agents fall into loops: no clear next step, so they repeat the same retrieval action, chewing through context on content they already have, until the whole thing stalls out or runs the budget dry.
Every token that enters the window is a choice someone made, whether they meant to or not. Pass everything forward by default, and that default is exactly what breaks long sessions.
The four failure modes that compound as sessions extend
Four things go wrong, and they don't happen one at a time. They stack.
Token bloat comes first, chronologically and causally. Raw, unconverted, partly redundant web content piles up in the window, and it doesn't just sit there quietly. It drags down the model's attention to everything else in the context, including the good stuff.
Lost-in-the-middle burial follows close behind. As more gets appended, earlier facts get pushed toward the middle of the context, right where model attention is weakest. Something the agent found in step 2 can be functionally invisible by step 12, even though it's technically still there.
Memory staleness is its own animal. Web content retrieved early in a session might be out of date by the time the agent gets around to using it. An agent running a 40-step research loop can be reasoning over information that's hours old and treating it like it's fresh off the page. This bites hardest in competitive intelligence, pricing research, or anything news-adjacent, where the underlying pages change while the agent is still working.
Context poisoning is the one people underestimate, and it's the one worth losing sleep over. OWASP's top LLM risk for 2025 is prompt injection, including the indirect kind, where malicious instructions get embedded in an external source like a scraped web page. The model doesn't know the difference between data and a command. If a page contains instructions dressed up as content, the model can end up following them. An agent that fetches an adversarially crafted page mid-session can have the rest of its context corrupted from that point forward. This is a scenario that shows up in practice, not one dreamed up in a threat model. It's the listed top vulnerability, full stop.
None of these run in isolation. Bloat makes burial worse. Staleness means the buried content isn't just hard to find, it's also wrong. And poisoning exploits the exact weakness that bloat and burial create: an agent already struggling to tell what matters is an agent that can't tell what's trustworthy either.
Why bigger context windows do not solve the problem and iterative retrieval does
Given a 1-million-token window, the tempting conclusion is that long-session coherence is basically solved. That conclusion is wrong, and the BEAM benchmark was built specifically to prove it. Tested at 128K, 500K, 1M, and 10M token scales, BEAM is designed so a bigger window can't cheat its way to a better score. What it measures is what a system does with volume, not whether it can hold volume in the first place. Those are different skills, and only one of them matters for research quality.
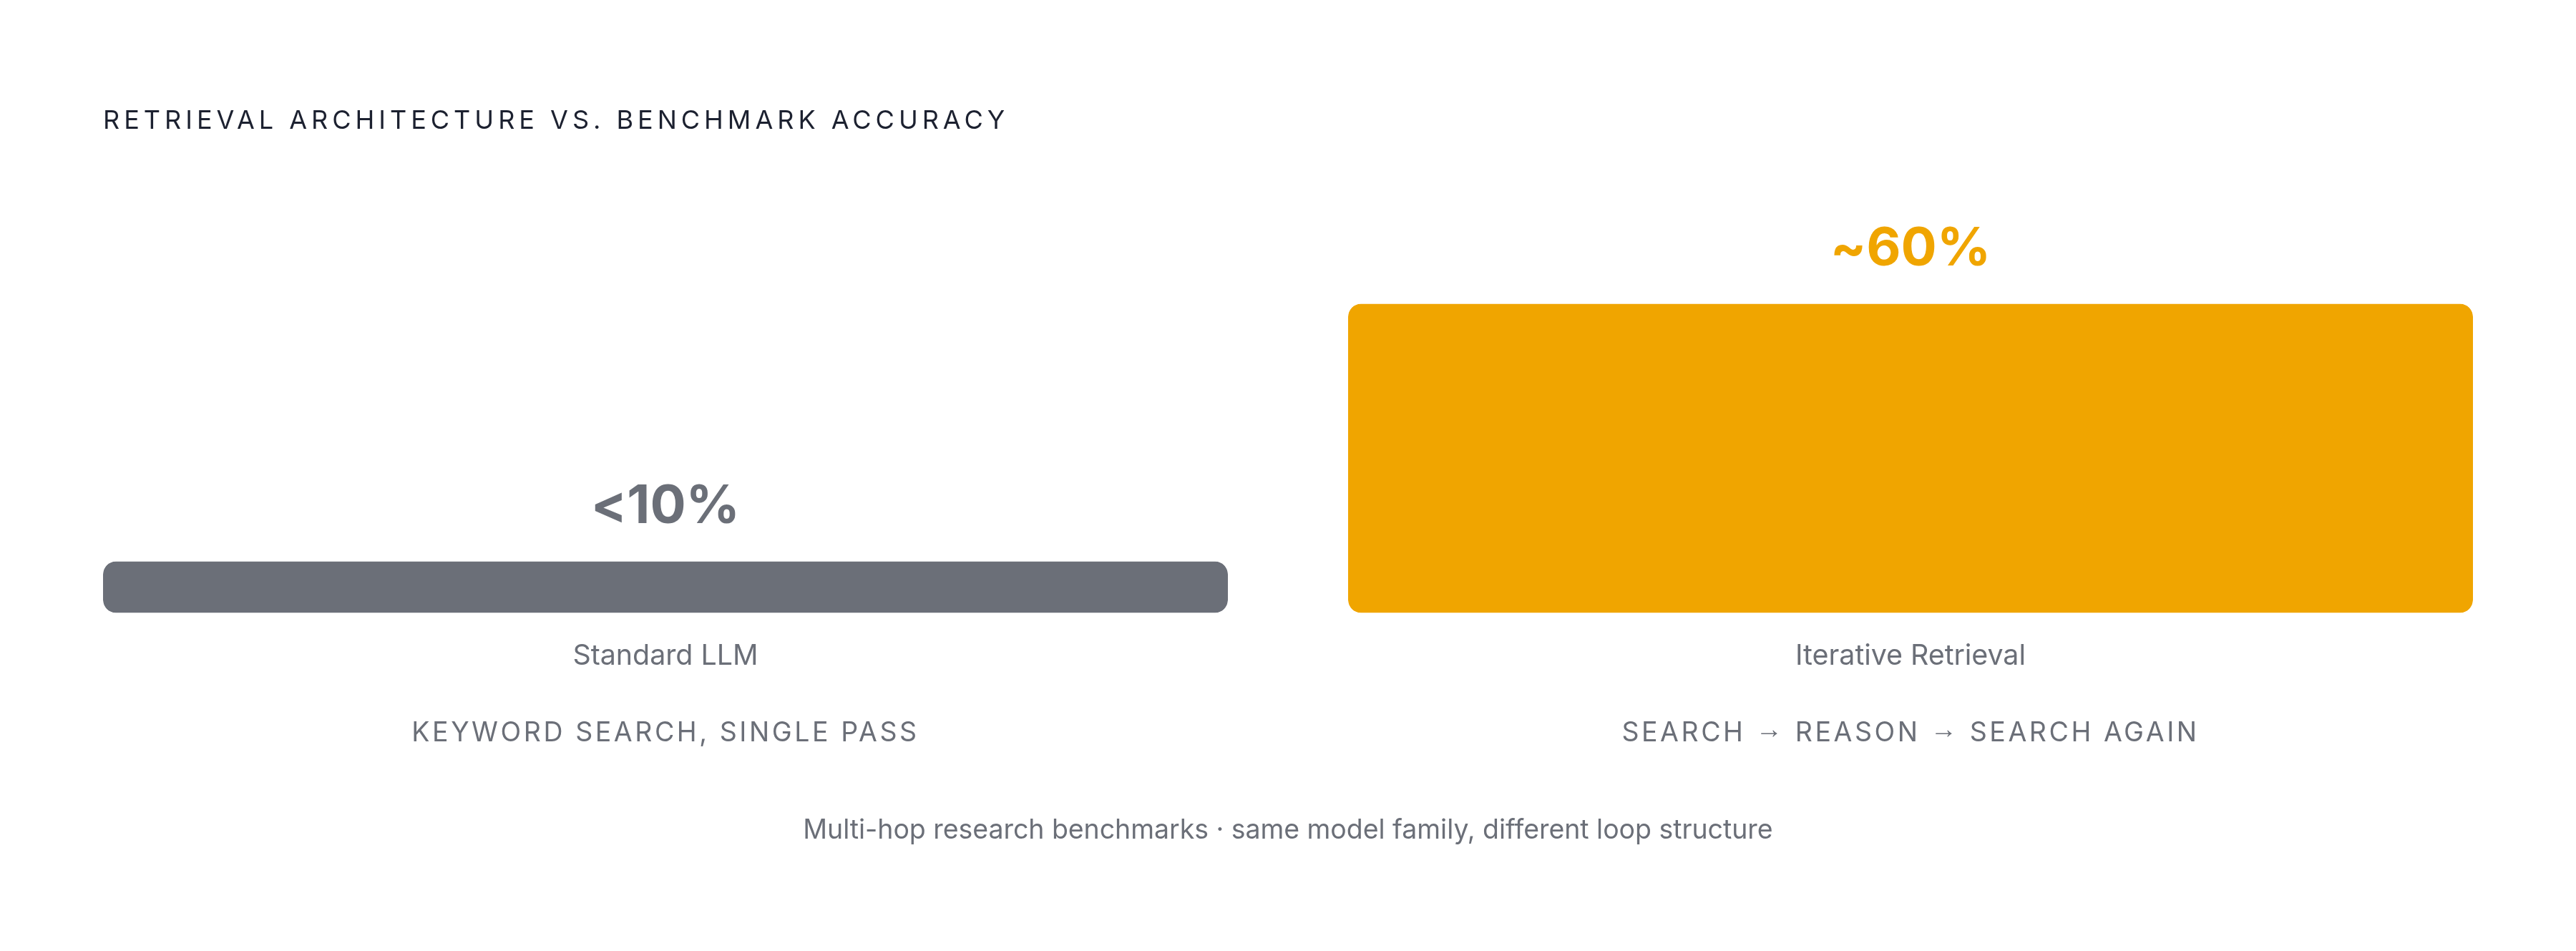
A 2025 survey on agentic deep research put a number on the gap. Standard LLMs relying on basic keyword search scored below 10 percent on complex, multi-hop research benchmarks. Systems built around iterative retrieval, meaning search, reason, search again, scored dramatically higher on the same benchmarks. Same model family in some cases, wildly different outcome, because the difference wasn't intelligence. It was architecture.
Iterative retrieval means the pipeline fetches selectively at each step instead of accumulating everything up front. The specific tool matters less than whether it can loop: search a little, think a little, search again based on what the thinking turned up. That loop also solves lost-in-the-middle almost as a side effect, since content fetched for the current step can sit at the head of the context, right where attention is strongest, instead of getting buried under everything that came before.
The real question was never how big a window a system can fill. It's what the agent should be reading right now, at this exact step. That's context engineering as active curation. Passive accumulation is the default, and it's also the failure mode. Pick the loop over the pile, every time.
The three memory tiers that production agent pipelines use
Production agent systems generally split memory into three tiers, and each one does a different job.
Working memory is the live context window itself: conversation history, the last several turns, whatever tool outputs are currently active. Depending on the model, this can span tens of thousands to hundreds of thousands of tokens. Left alone, it saturates, and it has to be actively managed or it turns into the token-bloat problem all over again.
Long-term semantic memory lives in a vector database, storing embeddings of facts, summaries, and past session outputs. It gets searched by relevance when needed, not carried around in full. This is where distilled knowledge lives, not raw material.
Structured episodic memory is a relational store: discrete facts, entity attributes, confirmed findings, queried by key rather than by similarity search. If the agent needs to know what it found about Company X's pricing at step 4, this is where that lives, and it doesn't need a similarity score to find it.
Web content doesn't belong sitting around in working memory across multiple steps. It's too big and too noisy for that job. Only distilled, typed facts earn a place in structured memory, and raw pages should mostly disappear once the turn that needed them is over. At each turn, a retrieval pipeline runs vector search, keyword search, and structured lookups in parallel, merges the results, and builds the working context fresh. The agent never drags its full history forward wholesale.
Selective retention: deciding what the agent writes to memory and what it discards
The default write policy in most systems is "append everything," and that default is where most of the bloat problem actually starts. Selective retention is the fix. It means being deliberate, almost stingy, about what earns a spot in memory.
In practice, that looks like a few concrete rules. Only confirmed, task-relevant facts get written to long-term memory, not raw page dumps, not full reasoning traces, not verbatim tool outputs. Facts get typed at write time, tagged with entity, claim, timestamp, source URL, and confidence, so retrieval later can filter by type instead of scanning everything stored. And when a fact gets superseded, it gets updated or deleted, not left sitting next to its replacement to confuse things later.
Mem0's 2026 approach is a useful example of this in action. It extracts facts in a single pass and writes them without overwriting or deleting prior entries, using hash-based deduplication only to catch exact duplicates. Tested against LoCoMo and LongMemEval, it scored in the low-to-mid 90s on both, using a fraction of the token cost that full-context approaches burn through. The two biggest jumps came in temporal reasoning and multi-hop reasoning, the exact two capabilities that degrade fastest in long web research sessions. That's not a coincidence. It's the whole point of selective retention.
A separate line of research, Fine-Mem, tackles a subtler problem: figuring out which specific memory write actually helped. Its Chunk-level Step Reward gives feedback on individual memory operations as they happen, rather than waiting until the end of the task to see if things worked out. That immediate feedback loop produces sharper write decisions over time.
Staleness needs its own fix baked into the write policy. Web-sourced facts should carry a retrieval timestamp and something like a confidence decay parameter, so a downstream reasoning step can weigh how fresh a fact is alongside how relevant it is. A fact from step 2 shouldn't get treated the same as a fact from step 38 just because they're both technically "in memory."
Structured retrieval: how agents find the right memory at the right reasoning step
Retrieval is a repeated process, not one query fired once. It's a multi-signal operation that runs fresh at every reasoning step, and it usually needs a few different tools working together, not one clever search box.
Vector search finds facts that mean something similar to the current query, even if the wording doesn't match. Keyword search catches what vector search tends to miss: exact entity names, URLs, quoted strings. Structured lookup skips similarity scoring entirely and just retrieves a typed fact by key, like pulling up exactly what was found about Company X's pricing back at step 4. Skip any one of these three and there's a category of query the pipeline will quietly get wrong.
Hybrid search, combining vector and keyword, is standard now in production vector databases. Pinecone offers managed hybrid search with namespace isolation for multi-tenant setups. Qdrant runs high-performance vector similarity search with payload filtering built in. Either can sit at the retrieval layer of a tiered memory pipeline, and the choice matters less than making sure both signal types are covered.
Where the retrieved fact lands in the context matters just as much as whether it gets retrieved at all. Facts relevant to the current step belong at the front or back of the working context, not tacked onto the middle of a growing pile of history. That placement decision is a direct countermeasure to the lost-in-the-middle problem the research documented.
Reflective Memory Management, published at ACL 2025 out of Google Cloud AI Research and Arizona State University, tackles a related issue: retrieval that's too rigid to adapt as a session goes on. It works through two mechanisms. Prospective Reflection summarizes dialogue history at varying levels, whole utterances, full turns, entire sessions, into a personalized memory bank, instead of chopping everything into fixed-size chunks regardless of what's actually in them. Retrospective Reflection refines retrieval on the fly, using a lightweight reranker that learns from how the model actually used past retrievals, without needing labeled training data. Together, they pushed accuracy up by more than 10 percent over memory-free baselines on tested benchmarks.
For web research specifically, retrieval also needs a staleness filter. A fact retrieved in the first ten minutes of a session shouldn't get treated as gospel in a reasoning step happening an hour later. It should get flagged, or re-checked, before it's trusted again.
Working memory management as an active, learned policy rather than a heuristic rule
Most pipelines running today manage working memory with simple rules of thumb: summarize every N turns, drop tool outputs older than M steps, truncate the middle when things get too long. These rules work, right up until they don't. When they fail, they fail in ways that are genuinely painful to debug, because the rule doesn't know why it's cutting something. It just cuts, the way a lawnmower doesn't know it's about to hit a garden hose.
Heuristics are a stopgap, not a strategy, and treating them as a finished solution is the mistake most teams are still making. The alternative gaining ground treats context curation as something the agent learns to do, not a fixed procedure bolted on from outside. MemAct, out of a research group spanning Beijing Jiaotong University, Hithink Research, HKUST(GZ), Huawei Noah's Ark Lab, and Peng Cheng Lab, frames working memory management as in-place editing, deletion and insertion, that the agent learns to perform through reinforcement learning. The results are notable: a 14-billion-parameter model trained this way matched the accuracy of models sixteen times its size, while cutting average context length by more than half. The learned strategy adapts to whatever model is running it and holds up across tasks of different complexity, because it's a capability the agent developed, not a rule someone hardcoded.
Fine-Mem adds a piece to this puzzle with its Chunk-level Step Reward mechanism. It traces which stored memory items actually got used in later reasoning, and assigns credit accordingly, so the agent learns which write and delete decisions actually mattered and which were just noise.
HiAgent splits memory management by scope: current subgoal context handled separately from summarized past subgoals, rather than dumping everything into one flat pool and hoping the retrieval layer sorts it out.
For teams not ready to build a learned policy from scratch, the heuristic version of the same idea is straightforward enough: prune aggressively, turn by turn. Delete what's already been used and confirmed. Write a compressed summary in its place. Never let raw tool output survive more than one turn. It's not as elegant as a learned policy, but it captures the same instinct: memory management as something the agent does on purpose, not something that happens to it.
How web data format choices determine whether memory management can work at all
Every idea above, selective retention, structured retrieval, tiered memory, rests on one assumption: that the content flowing into the pipeline is parseable and consistent enough to reason about in the first place. Raw HTML breaks that assumption before any of the memory architecture even gets a chance to run. This is the part teams skip, and it's the part that decides whether everything else in this piece even applies.
A fact-extraction step can't type a claim, timestamp it, and file it into structured memory if it's still buried in nested divs, tracking scripts, and layout markup. Selective retention depends on identifying what's worth keeping, and that identification step depends on the content already being in a form a model can read cleanly, ideally something close to Markdown rather than raw markup. Structured retrieval depends on facts being extracted consistently enough that a key-based lookup actually returns the same kind of thing every time it's queried. None of that works if the underlying page format is a moving target, changing shape between scrapes the way non-deterministic rendering tends to produce.
The format decision is a core part of memory architecture, not some separate technical detail sitting off to the side. It's the foundation the whole thing sits on. Get clean, structured, consistent content in, and selective retention, structured retrieval, and tiered memory all have a fighting chance. Feed the pipeline raw HTML soup instead, and no amount of clever memory engineering downstream is going to save it.